Verified result

497.9tok/s

Verified text generation speed
ClassA

Performance class

This run ranks #3 among 53 verified runs on VRAM Check.

Ranks compare published benchmark runs, not unique GPU models. The same GPU model may appear more than once. Comparison for TinyLlama 1.1B (Q4_K_M) / Q4_K_M, not overall AI performance.

Tasks to explore: Coding · General chat · Math / reasoning · Embeddings.

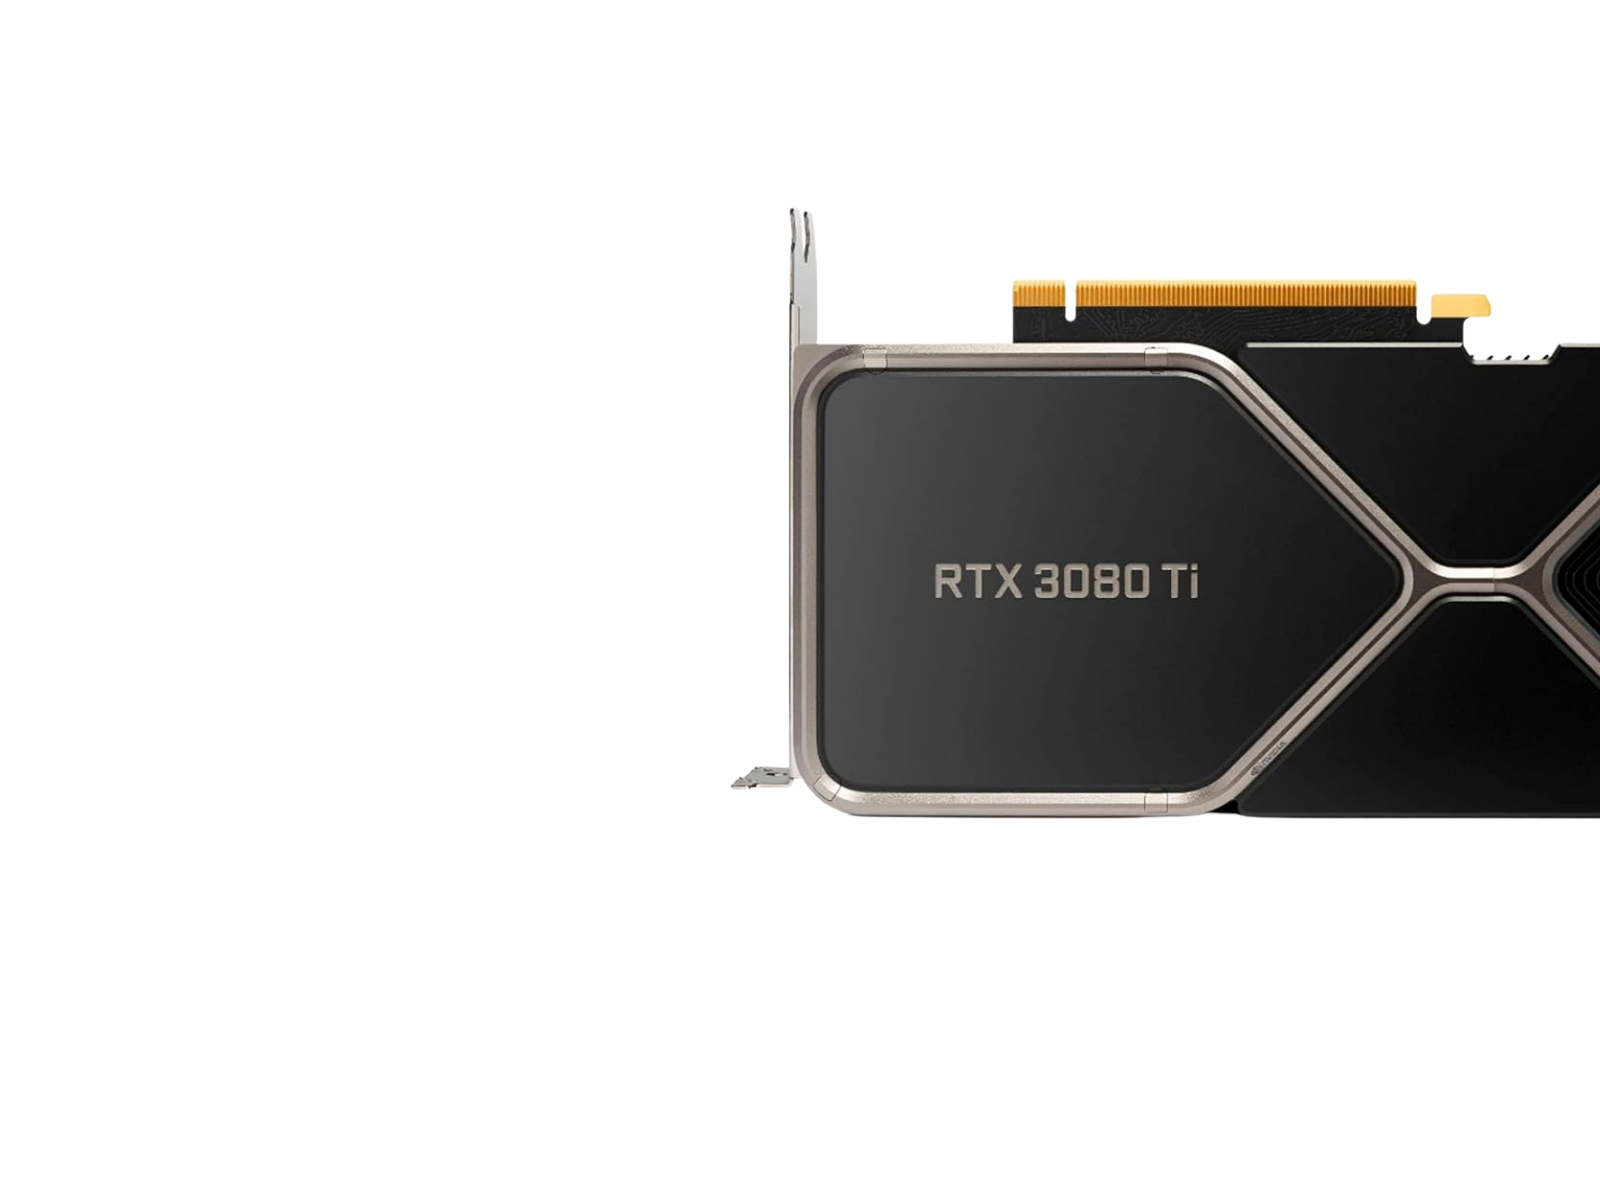
GeForce RTX 3080 Ti, user-prepared illustration

User-prepared RTX 3080 Ti illustration. Board design and framing may differ.

NVIDIA GeForce RTX 3080 Ti
ModelTinyLlama 1.1B (Q4_K_M)
QuantQ4_K_M
DateMar 19, 2026
LeaderboardThis run on VRAM Check
#3
This run ranks #3 among 53 verified runs on VRAM Check.

2.6 tok/s is the gap to the next podium place.

Next place · #2+2.6 tok/sNeeded to move up
Global lead+287.2 tok/sNeeded to reach #1
Reach Class S+102.1 tok/s600 tok/s threshold
Estimated model matchesChoose a task to explore
Coding
General chat
Math / reasoning
Embeddings

See the sections below for model suggestions and possible next steps.

How to read this resultWhy this result can be ranked
What this status meansVerified and ranked

The computer completed the standard test, passed every required check, and earned a public ranking.

Why we trust this resultVerified GPU (Leaderboard Eligible)

This is the verified text generation speed used to rank this computer.

vulkan backendDiscrete GPU memoryMain limit: System RAM

What your score means.

These measurements show how quickly the model reads, starts answering, and continues writing, plus how consistent the test was.

Performance mapSee where this score sits.
Class A
Prompt reading speedHow quickly the model reads your prompt before it starts answering. Higher is better. The technical name is prefill throughput.
26309.3 tok/s
First output delayHow long the model takes to produce its first piece of the answer after reading the prompt. Lower is better. This is not total request time.After the prompt is read
25 ms
Memory available to modelsThe practical amount of memory this test can use for model data. It helps determine which model sizes should fit.
10.3 GB
Measured test timeHow long the representative measured pass took. Warm-up and setup time are kept separate.
2s
Result consistencyHow much the repeated tests differed. Smaller percentages mean the result was steadier and easier to reproduce.Writing / first response
1.03% / 0.76%

Find your next model.

Choose a task, compare memory requirements, and open a model to explore compatible hardware.

77 of 139 catalog profiles meet the memory estimate.

Three points across the memory range, not a model-quality ranking.

Memory checkCatalog estimate

Falcon3 1B Instruct

Within the planning budget.

1 GB model estimate10.3 GB budget
9.3 GBmemory margin
Quantization
Q4_K_M
System RAM
15.9 / 5 GB required
Speed on this model
Not measured
Explore model & compatible GPUs

Memory fit is a starting point, not a speed guarantee. Context length, runtime and other applications can change actual memory use. Only the benchmark model was timed.

Task coverage and planner estimates
4/4clear now
Has estimated fits 4Close 0Needs more 0
Runs well now4 types of tasks should run well
CodingGeneral chatMath / reasoningEmbeddings
Close, but may feel tightNothing is one small step away
No obvious next model group
Needs a stronger computerNo listed task is completely out of reach
No task is fully blocked

Compatibility estimates updated Oct 19, 2026. They combine this measured run with the model catalog; each suggested model was not benchmarked directly.

See all model categories4 categories
CodingEstimated fits available
45% of tracked models fit now
Works well nowCoding works well on this build

Good starting points: DeepSeek Coder V2 Lite · StarCoder2 15B · Gemma 4 12B Instruct.

What more headroom changesA targeted upgrade opens more options

The clearest next unlocks are GPT-OSS 20B · Devstral Small 2 24B · Codestral 22B.

No major blockerProjected from this measured run
General chatEstimated fits available
55% of tracked models fit now
Works well nowGeneral chat works well on this build

Good starting points: Phi-4 · Gemma 4 12B Instruct · Qwen 2.5 14B Instruct.

What more headroom changesA targeted upgrade opens more options

The clearest next unlocks are GPT-OSS 20B · Devstral Small 2 24B.

No major blockerProjected from this measured run
Math / reasoningEstimated fits available
34% of tracked models fit now
Works well nowMath / reasoning works well on this build

Good starting points: Gemma 4 12B Instruct · Ministral 3 14B Instruct · Qwen3 14B Instruct.

What more headroom changesA targeted upgrade opens more options

The clearest next unlocks are GPT-OSS 20B.

No major blockerProjected from this measured run
EmbeddingsEstimated fits available
100% of tracked models fit now
Works well nowEmbeddings works well on this build

Good starting points: Qwen3 Embedding 8B · mxbai-embed-large · Nomic Embed Text v1.5.

What more headroom changesAn upgrade adds breathing room

More capacity would make this task feel safer, but it would not unlock a new class of models yet.

No major blockerProjected from this measured run

What limits this computer first.

See the main constraint, the evidence behind it, and why the recommendation focuses there.

Main limitSystem RAM is the next thing likely to pinch

There is enough RAM to complete the test, but longer conversations, larger documents, and several local AI tasks at once will start using system memory first.

What hits first16 GB system RAM

The test completes, but heavier multitasking and longer conversations will start using RAM first.

What still worksCoding · General chat · Math / reasoning · Embeddings

The measured workload is stable today, so this is more about resilience than rescue.

Why we recommend thisPrioritize more RAM

More system memory makes the whole machine feel steadier once sessions get heavier.

Why this recommendationMore RAM improves stability under heavier real use

That is why the recommendation favors more RAM. It will make the whole setup feel less fragile during heavier real-world use.

No listed task is completely out of reachUse the model-specific comparison below to decide which capacity change is useful for your goal.
Technical proofWhy we trust this result
10 checks
Execution profileVerified GPU benchmark
Validation statusVerified
Run qualityStable
Methodologyv1.1
GPUNVIDIA GeForce RTX 3080 Ti
CPUAMD Ryzen 3 3100 4-Core Processor
VRAM / RAM11.8 / 15.9 GB
OSWindows 11 24H2 (Build 26100)
Client version0.1.0
DriverNot reported
Technical details and model explorer

The report above gives you the answer first. Open this area only when you want to compare individual models or inspect the repeated measurements behind the score.

Measure the computer in front of you.

Run the same benchmark and get a report grounded in your own hardware, workload conditions, and repeatable local inference.